# Setup your own private LLM server
### Requirements
**Hardware:**
Any hardware you'd like to use that has enough memory to support the model gguf file. I recommend a dedicated machine, even better would be in an isolated VM. Also, this is a server without gpu install. A system with a GPU would produce faster responses.
- This write-up uses:
```plaintext
1 old PC
64gb DDR4 memory
AMD Ryzen 5 2600 Six-Core 12 Threads
32gb storage for OS
128gb storage for models and tools
```
**Operating System and Build Dependencies**
**Base OS**: Ubuntu 26.04.1 LTS (Resolute Raccoon)
- Verify the installed OS version:
```plaintext
grep -i '^VERSION=' /etc/os-release
```
- Install the required build dependencies:
```plaintext
sudo apt update
sudo apt install -y build-essential cmake libssl-dev
```
### Setup Steps
**Top level directory**
First create a directory tree to store everything
```plaintext
u1@mimas:~$ pwd
/home/u1
u1@mimas:~$ mkdir -p ai/models
u1@mimas:~$ tree ai
ai
└── models
2 directories, 0 files
u1@mimas:~$ cd ai
u1@mimas:~/ai$
```
**Clone llama.cpp**
```plaintext
u1@mimas:~/ai$ git clone https://github.com/ggml-org/llama.cpp
Cloning into 'llama.cpp'...
remote: Enumerating objects: 139854, done.
remote: Counting objects: 100% (67/67), done.
remote: Compressing objects: 100% (32/32), done.
remote: Total 139854 (delta 40), reused 35 (delta 35), pack-reused 139787 (from 3)
Receiving objects: 100% (139854/139854), 446.38 MiB | 42.59 MiB/s, done.
Resolving deltas: 100% (100183/100183), done.
u1@mimas:~/ai$
```
**Download Qwen**
```plaintext
u1@mimas:~/ai$ wget -O models/Qwen3-32B-Q6_K.gguf \
https://huggingface.co/qtum/Qwen3-32B-GGUF/resolve/main/Qwen3-32B-Q6_K.gguf
```
Substitute the .gguf file to download a different model.
**Build llama.cpp**
```plaintext
u1@mimas:~/ai$ cd llama.cpp
u1@mimas:~/ai/llama.cpp$ cmake -B build
- -- The C compiler identification is GNU 15.2.0
- -- The CXX compiler identification is GNU 15.2.0
***** output cut for brevity *****
- -- Configuring done (7.4s)
- -- Generating done (0.3s)
- -- Build files have been written to: /home/u1/ai/llama.cpp/build
u1@mimas:~/ai/llama.cpp$
u1@mimas:~/ai/llama.cpp$ cmake --build build -j --target llama-cli llama-server
[ 0%] Building CXX object ggml/src/CMakeFiles/ggml-base.dir/ggml.cpp.o
[ 0%] Building C object vendor/hash/CMakeFiles/vendor-hash.dir/xxhash/xxhash.c.o
[ 0%] Building CXX object vendor/hash/CMakeFiles/vendor-hash.dir/sha1/sha1.c.o
[ 0%] Building C object ggml/src/CMakeFiles/ggml-base.dir/ggml-alloc.c.o
[ 0%] Provisioning UI assets
[ 0%] Building CXX object common/CMakeFiles/llama-common-base.dir/build-info.cpp.o
[ 2%] Building CXX object vendor/hash/CMakeFiles/vendor-hash.dir/hash.cpp.o
[ 2%] Building CXX object ggml/src/CMakeFiles/ggml-base.dir/ggml-opt.cpp.o
***** output cut for brevity *****
[ 91%] Built target llama-common
[ 95%] Built target server-context
[ 97%] Built target llama-server-impl
[100%] Building CXX object tools/server/CMakeFiles/llama-server.dir/main.cpp.o
[100%] Linking CXX executable ../../bin/llama-server
[100%] Built target llama-server
u1@mimas:~/ai/llama.cpp$
```
**Verfiy binaries working**
```plaintext
u1@mimas:~/ai/llama.cpp$ ./build/bin/llama-cli --version
version: 0.6.0-dev (build 11606, commit 1b70350c9)
built with GNU 15.2.0 for Linux x86_64
u1@mimas:~/ai/llama.cpp$ ./build/bin/llama-server --version
version: 0.6.0-dev (build 11606, commit 1b70350c9)
built with GNU 15.2.0 for Linux x86_64
u1@mimas:~/ai/llama.cpp$
```
**Serve the model**
```plaintext
u1@mimas:~/ai/llama.cpp$ ./build/bin/llama-server -m /home/u1/ai/models/Qwen3-32B-Q6_K.gguf -ngl 0 -c 40960 --host 0.0.0.0 --port 8080
warning: no usable GPU found, --gpu-layers option will be ignored
warning: one possible reason is that llama.cpp was compiled without GPU support
warning: consult docs/build.md for compilation instructions
0.00.003.992 I srv llama_server: initializing ...
0.00.004.035 I cmn common_param: common_params_print_info: verbosity = 3 (adjust with the `-lv N` CLI arg)
0.00.004.814 W srv llama_server: security: no API key is set and CORS allows all origins (see https://github.com/ggml-org/llama.cpp/pull/25655)
0.00.007.049 I srv load_model: loading model '/home/u1/ai/models/Qwen3-32B-Q6_K.gguf'
0.00.614.341 W load: control-looking token: 128247 '' was not control-type; this is probably a bug in the model. its type will be overridden
0.05.613.885 I cmn init: llama threadpool init, n_threads = 11
0.09.580.894 I srv load_model: initializing, n_slots = 4, n_ctx_slot = 40960, kv_unified = 'true'
0.09.590.423 I srv llama_server: model loaded
0.09.590.433 I srv llama_server: listening on http://0.0.0.0:8080
```
Wait for "llama_server: listening on"
**Check/Use service url**
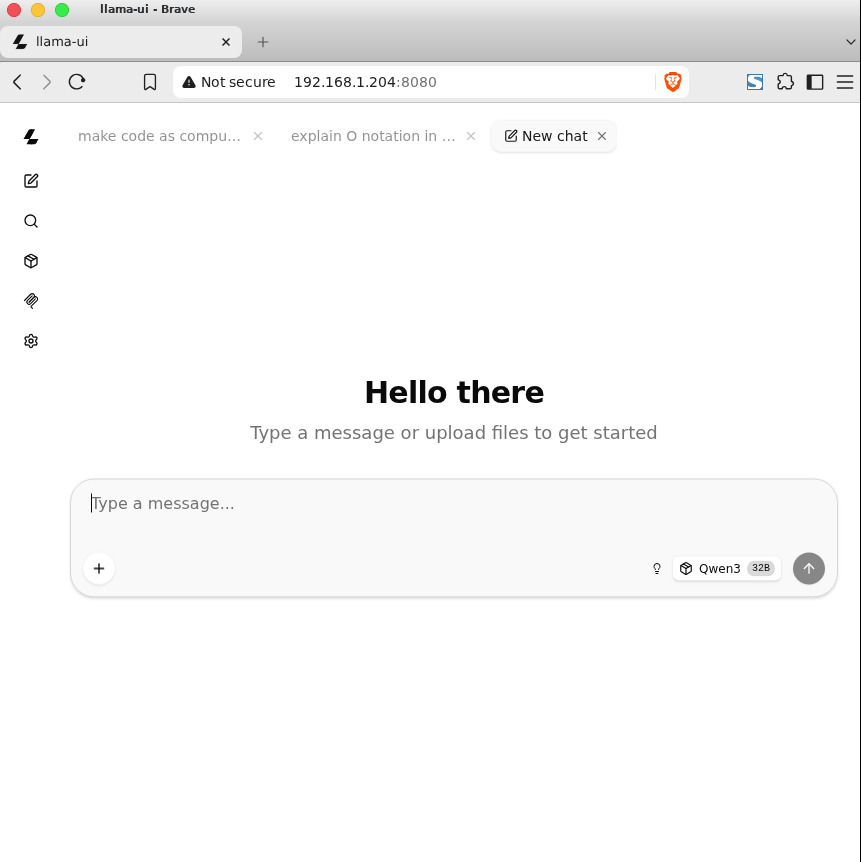
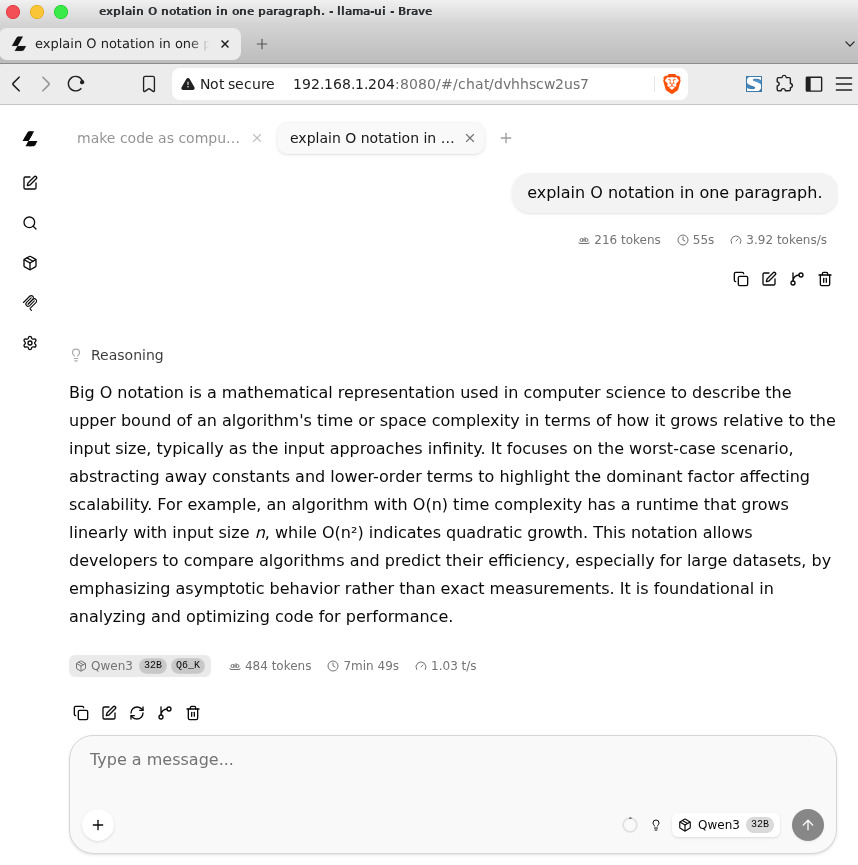 Substitute your host:port accordingly.
---